A common misconception in 2026 is that giving a reasoning model more thinking tokens always guarantees a better answer. Recent research—including arXiv:2604.10739 (When More Thinking Hurts)—demonstrates that overthinking in extended chains of thought can actually degrade accuracy and inflate latency once a task passes its optimal compute knee (Blocksize).
The Logarithmic Scaling Curve—and Its Plateau
On verifiable problems such as competition math and algorithmic coding, accuracy rises roughly with the logarithm of test-time compute (Blocksize). However:
- Once the curve flattens, extra thinking tokens introduce self-doubt loops where the model talks itself out of a correct initial deduction.
- Visible reasoning traces are not guaranteed proofs: A model can produce a plausible-looking chain of thought that still arrives at a wrong conclusion (Blocksize).
How to Prevent Overthinking in Production
1. Benchmark the “Knee” on Your Eval Set: Test low, medium, and high thinking budgets on 50–100 real examples and stop increasing the budget once accuracy plateaus (Blocksize).
2. Verify the Output, Not Just the Trace: Always validate final outputs with unit tests, compilers, or JSON schemas rather than trusting a long reasoning trace.
Internal & Further Reading
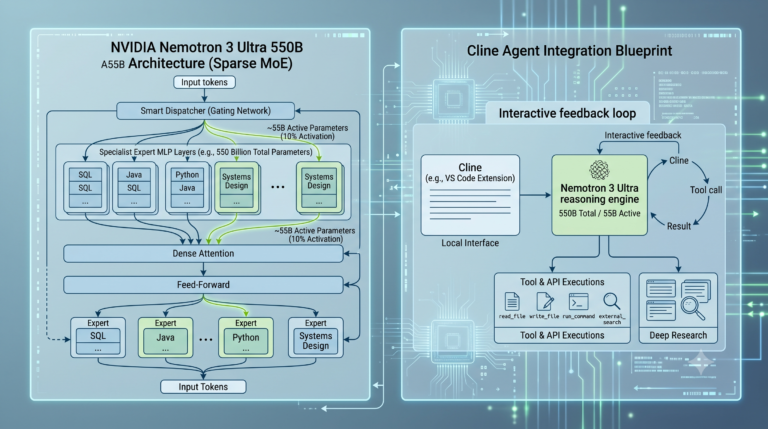
See how we apply structured workflows in NVIDIA Nemotron 3 Ultra 550B A55B Guide.
Frequently Asked Questions
What is LLM overthinking?
Overthinking occurs when a reasoning model spends excessive test-time compute generating repetitive or self-contradictory steps that lower accuracy instead of improving it (arXiv).
Can you trust a reasoning model’s visible chain of thought as an audit proof?
No—visible thinking is a helpful debugging signal, not a mathematically faithful guarantee of how the final answer was produced (Blocksize).


+ There are no comments
Add yours