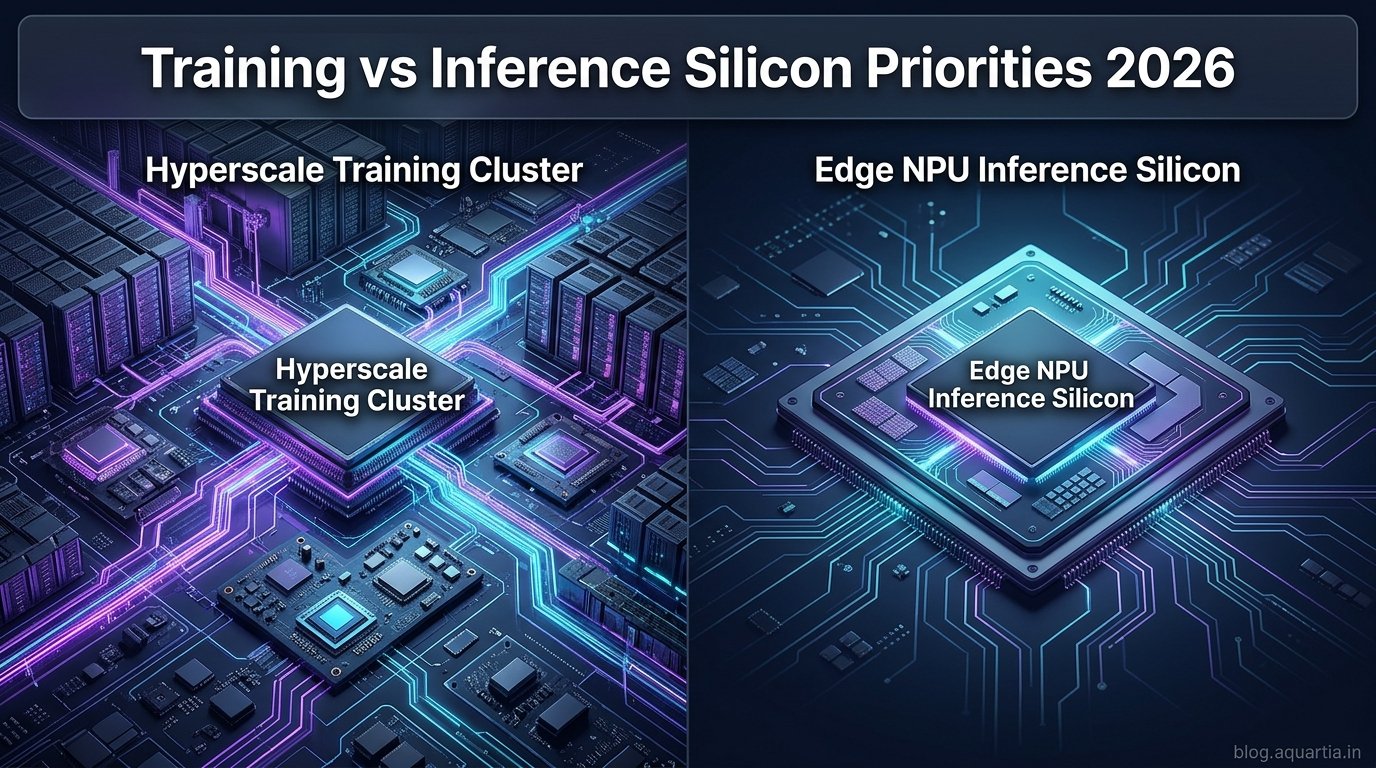
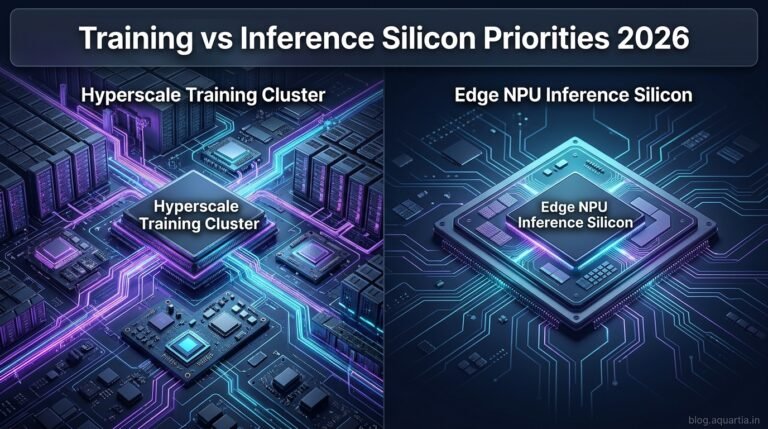
Early AI hardware treated training and inference as variations of the same GPU workload. In 2026, semiconductor architecture is splitting along clear workload boundaries (Alpinum Consulting, AIMultiple).
Training vs. Inference Silicon Priorities
| Priority | Frontier Training Clusters | Data-Center & Edge Inference |
|---|---|---|
| Primary Goal | Maximum FLOPS, massive HBM capacity, multi-node interconnect | Low deterministic latency, cost/watt, thermal efficiency (Alpinum Consulting) |
| Cooling & Power | Liquid-cooled racks (e.g., Helios, Vera Rubin) | Air-cooled PCIe cards (e.g., Intel 350W Crescent Island) or low-wattage NPUs (AIMultiple) |
| Precision Support | FP8, FP4, BF16, FP64 (scientific HPC) | INT4/FP4/FP8 quantized weights |
Rise of Custom ASICs, Edge NPUs, and RISC-V
Hyperscalers are deploying custom ASICs tailored to internal inference traffic, while automotive, medical, and industrial devices rely on edge NPUs and RISC-V accelerators for local, privacy-preserving execution (Alpinum Consulting).
Internal & Further Reading
See how quantized small models take advantage of edge silicon in our SLMs vs. LLMs for Business Guide.
Frequently Asked Questions
Why can’t one chip architecture optimize both training and inference?
Training demands extreme inter-chip bandwidth and power budgets, whereas inference prioritizes low latency, lower cost per token, and often air-cooled or battery-constrained operation (Alpinum Consulting).

+ There are no comments
Add yours